Next.js
 Python
 Cloud
 Security
 Ruby
 Cpp
Article
Reducing C++ template bloat with a smaller type-dependent boundary
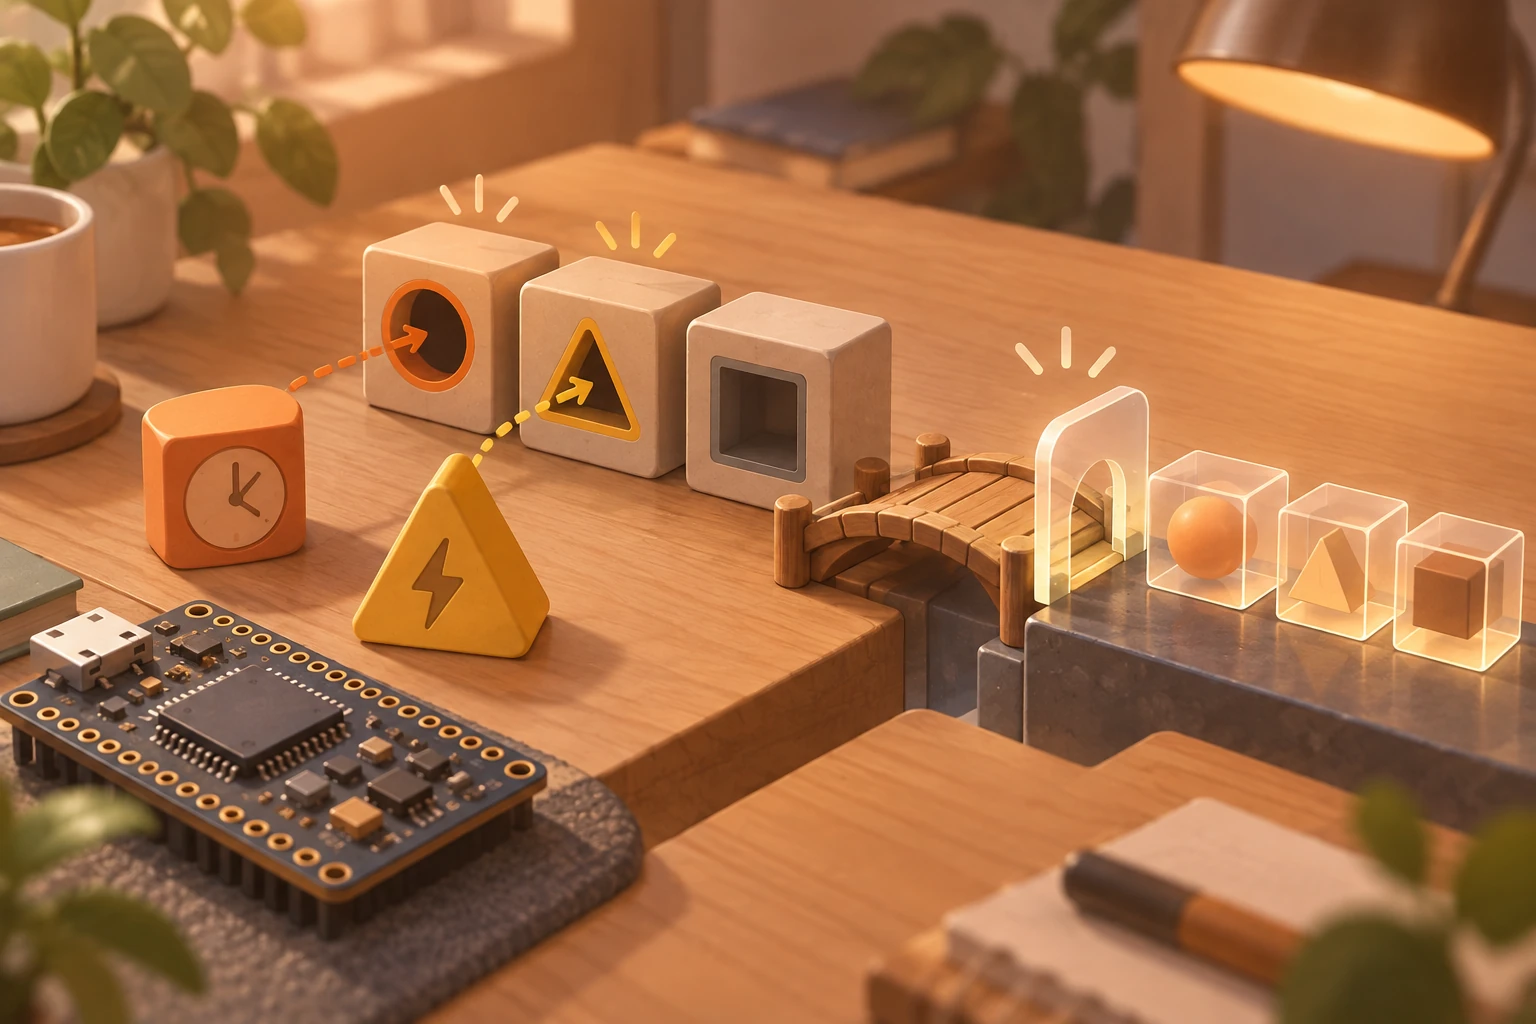
A large template can be instantiated for each type even when little of its logic depends on that type. A shared worker taking std::span can narrow that boundary, but lifetime, evaluation order, and optimized output determine whether the refactoring pays off.
Share
Koharu's reading tip
Which parts of a long function actually need the type? Look at the data and its lifetime at the shared boundary to find a useful place to split.

Templates can remove repetition from C++ source without removing the same repetition from an executable. That distinction matters when a long function needs its template parameter in only a small part of its implementation.
On September 25, 2026, the ISO C++ Blog highlighted a technique for reducing this duplication by separating type-dependent work. How much implementation can be shared while keeping a flexible entry point?
C++20's std::span provides a useful way to explore that boundary. The decision depends on which information the shared implementation needs, and which operations change behavior when moved.
Distinct lambda types can multiply otherwise shared work
Different template arguments produce different specializations of a function template. Lambdas make this especially easy to encounter: the C++ working draft defines a closure type as a unique, unnamed class type.
The distinction is between lambda expressions, not execution counts. Repeatedly evaluating the same lambda expression in a loop does not create a new type each time. Passing separately written lambda expressions to a template can introduce distinct types and therefore additional instantiations.
Specializations do not necessarily map one-to-one to machine-code bodies in the final executable. MSVC's /OPT:ICF merges identical COMDATs. It works on identical generated output; similarity in the intended algorithm is not enough. See the MSVC linker optimization reference.
An explicit shared function boundary offers another place to address duplication.
Use std::span to remove container types and lengths from the worker
A small template can obtain the required data and pass it to a larger, non-template worker. Raymond Chen's explanation of type-dependent factoring illustrates this by moving column retrieval to the entry point.
std::span views contiguous elements without taking ownership. Built-in arrays, std::array, and ordinary std::vector storage can supply such elements. The <span> header is available from C++20; MSVC requires /std:c++20 or later. See Microsoft's span documentation.
For example, a read-only worker could accept std::span<const Column>. Assuming live storage and the same Column element type, the boundary looks like this:
| Caller storage | Worker parameter type | Length representation |
|---|---|---|
std::array<Column, 3> |
std::span<const Column> |
Runtime value 3 |
std::array<Column, 8> |
std::span<const Column> |
Runtime value 8 |
std::vector<Column> |
std::span<const Column> |
Current element count |
Omitting the extent selects std::dynamic_extent. Container identity and array length no longer appear in the worker's type, allowing the same function to handle these inputs.
Conversely, templating the worker on N and accepting std::span<const Column, N> retains a dependency on the length. The design choice is which information to preserve at compile time and which to pass as runtime data. The span specification defines these template parameters and conversions.
This boundary shares contiguous data of a common element type. It does not automatically accommodate unrelated element types or replace arbitrary lambda behavior.
Moving data retrieval also changes ordering and lifetime requirements
Arguments must be ready before the worker starts. An original sequence of preparation, column retrieval, and processing can become retrieval, preparation inside the worker, and processing. Chen explicitly identifies this ordering change.
For example, retrieval that logs activity or reads external state may make that movement observable. If preparation throws, retrieval may now run where it previously did not. These are conditions to investigate in the application, rather than assuming that extracting a function preserves behavior.
Ownership is a separate constraint. The span specification places ownership elsewhere and describes how invalidating underlying pointers affects access through a span. If the caller owns a vector, its storage must remain valid until the worker finishes reading it.
Using the view only during a synchronous call and retaining it for later use require different lifetimes. Adding const does not extend the owner's lifetime.
Judge factoring by optimized code size and execution time
A single worker in source can still be inlined into callers. MSVC's __declspec(noinline) suppresses inlining, but it is a compiler-specific option to consider after inspecting generated output, rather than a default annotation for every shared function. See the MSVC noinline documentation.
A practical experiment is to choose one large template with suspected duplication and compare both versions using the same compiler, optimization settings, and target architecture. Measure code-section size alongside execution time for the affected operation. This separates the size outcome from the runtime consequences of changing the call boundary; it does not promise a particular reduction or speedup.
With MSVC, /DEBUG changes the default for /OPT:ICF, so a Debug-only comparison should not be generalized to a distribution build. /VERBOSE can report folded functions. See the linker optimization and diagnostic options.
The shareable implementation is the work that can run without knowing the concrete input type. Narrow that boundary, preserve retrieval order and storage lifetime, and evaluate the result with distribution settings. That gives a concrete way to address executable duplication while retaining a flexible template interface.
Source
- Title: Reducing C++ template bloat by factoring out type-dependent portions of the function -- Raymond Chen
- URL: https://isocpp.org//blog/2026/09/reducing-cpp-template-bloat-by-factoring-out-type-dependent-portions-of-the
Share
Related Articles
These articles share nearby categories or tags, so you can keep reading along the same thread.