Next.js
 Python
 Cloud
 Security
 Ruby
 Cpp
Article
AWS Lambda Kafka Queue mode: scaling beyond partitions without ordering
AWS Lambda now supports Queue consumption mode using Kafka share groups on compatible Kafka 4.2 or later clusters. It decouples parallelism from partition count, making ordering dependencies, idempotency, retries, and broker limits central to adoption.
Share
Koharu's reading tip
Before increasing concurrency, consider whether reversing event order still produces the right result. That is a separate requirement from handling duplicate delivery safely.

A backlog of image conversion jobs in Kafka needs more Lambda workers. Does adding processing capacity also have to mean changing the number of partitions in the topic? That coupling can become an awkward design constraint.
Announced on November 2, 2026, AWS Lambda Queue consumption mode offers a way to loosen it. The tradeoff is that processing order is no longer guaranteed, even within a partition.
Which workloads can accept that tradeoff? Following how share groups distribute work, handle redelivery, and interact with configuration and capacity limits gives us a practical basis for deciding.
Share groups change how a partition is shared
In the existing Stream mode, each partition belongs to one consumer within a consumer group. A topic with ten partitions therefore supports at most ten consumers actively consuming assigned partitions in that group. Exclusive assignment provides the basis for preserving order within each partition.
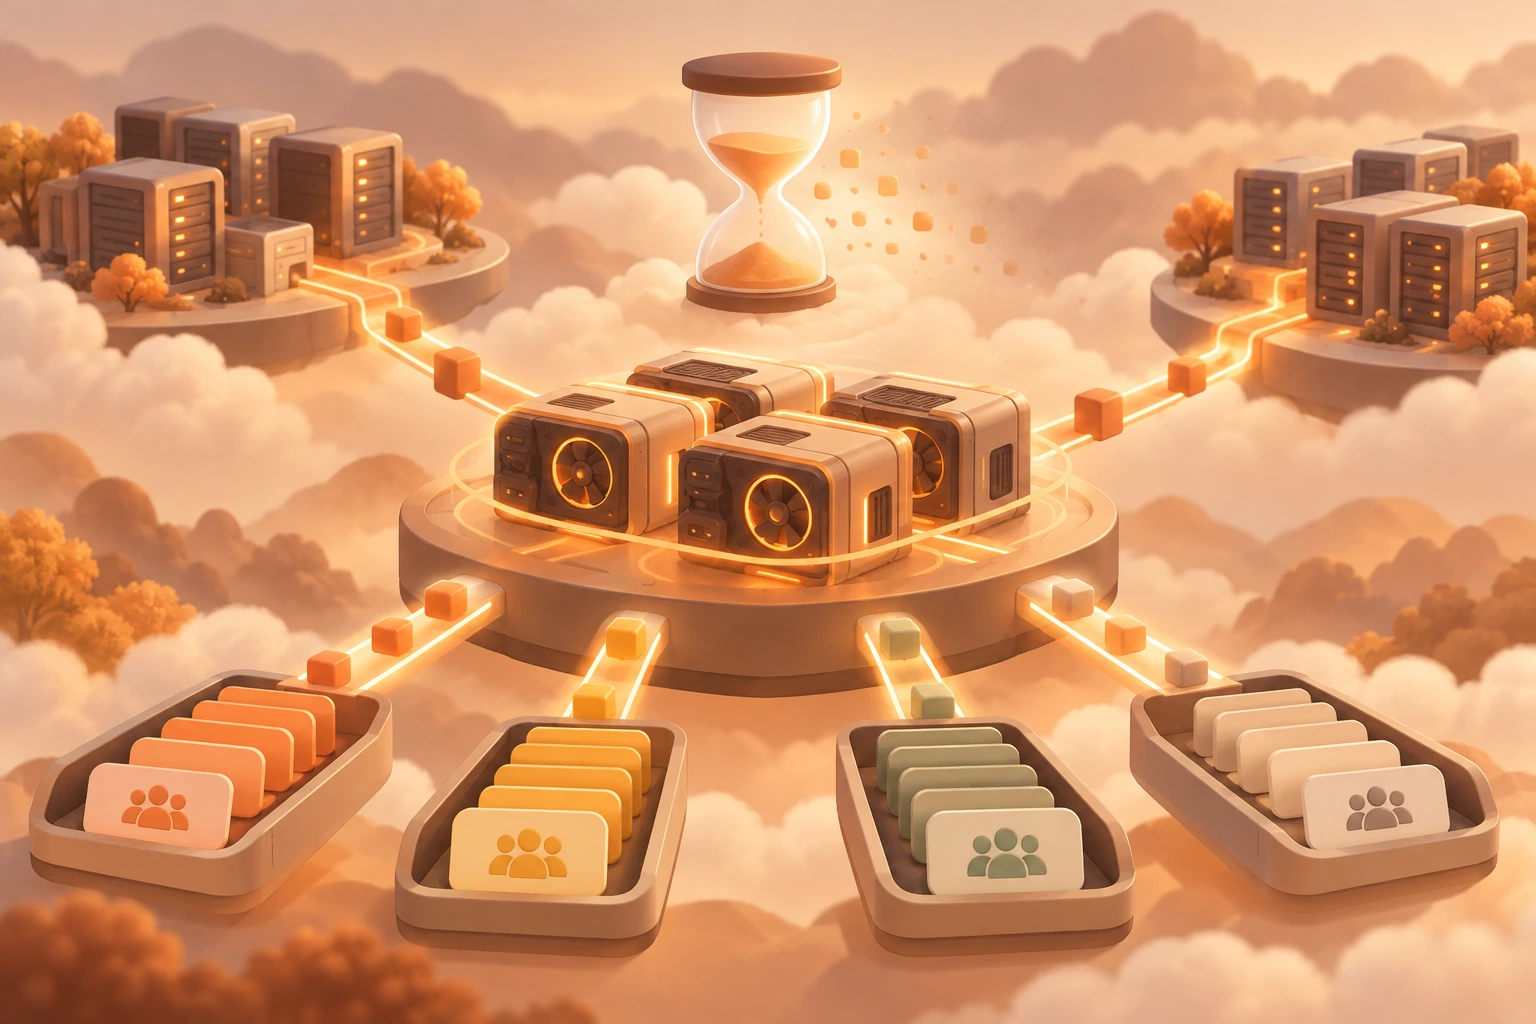
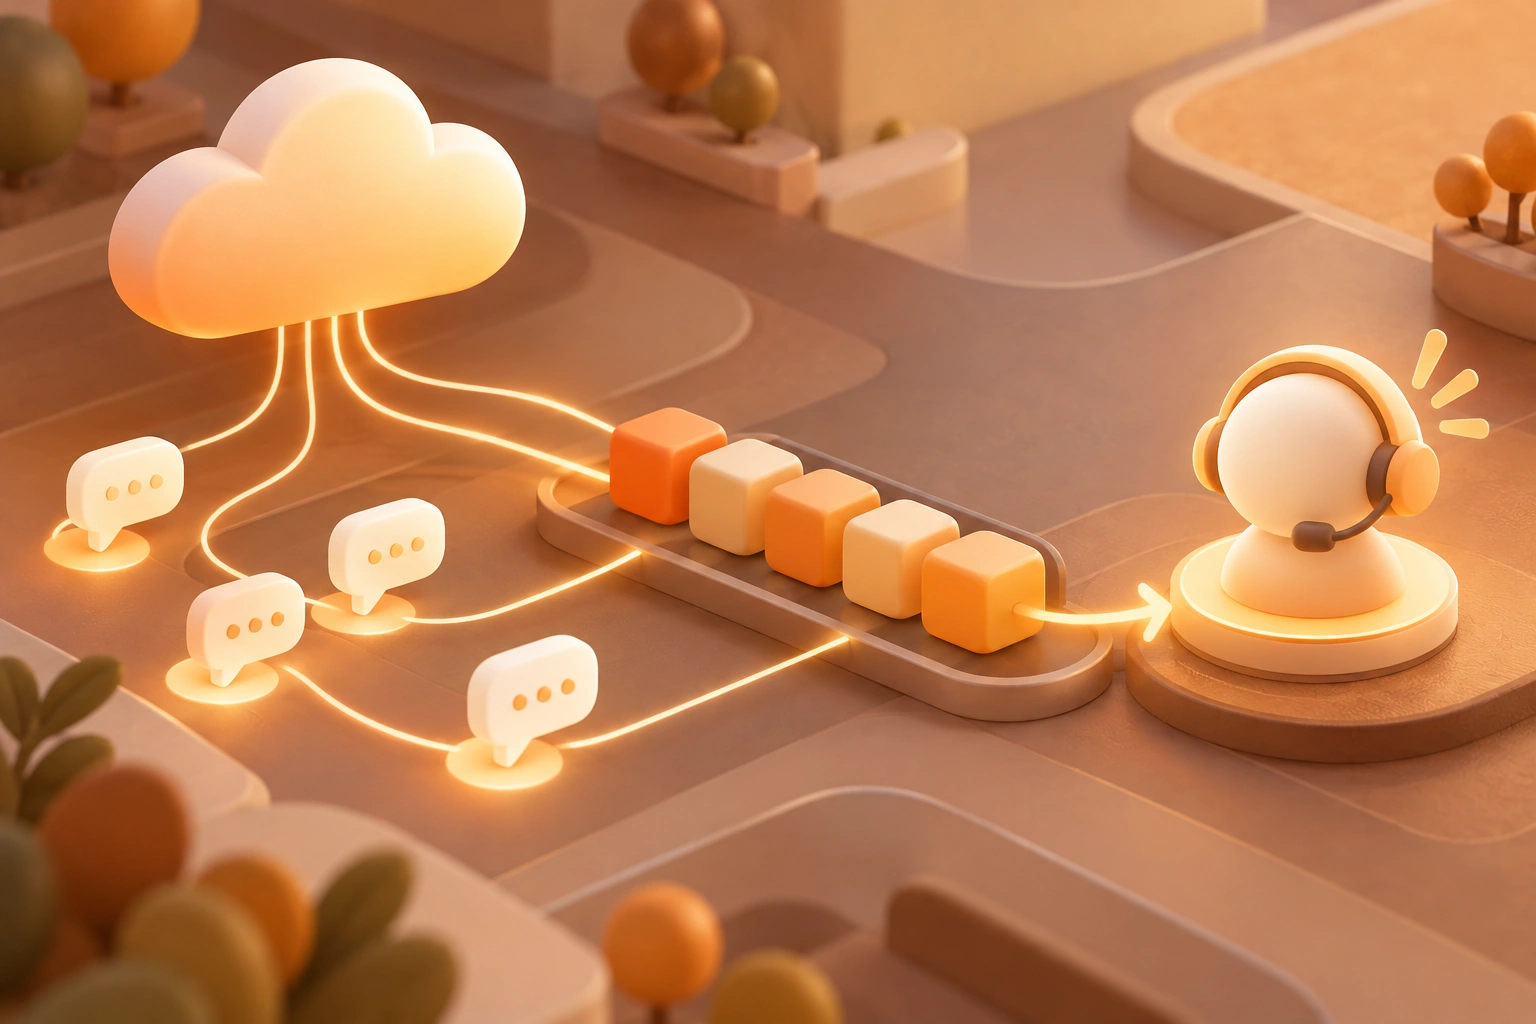
Queue mode uses share groups to let multiple consumers share a partition. Instead of reserving the entire partition, consumers acquire records under time-limited locks. The KafkaShareConsumer specification explicitly describes the exchange of ordering guarantees for more flexible work distribution.
An event poller is the Lambda component that fetches records and invokes the function. Queue mode allows more pollers without tying their count to the number of partitions. Independent image conversion jobs in a single partition can therefore be distributed across parallel function invocations.
The underlying Queues for Kafka feature became production-ready in Kafka 4.2. The Lambda update makes that consumption model selectable through an event source mapping, or ESM.
Independent jobs still need protection against duplicates
Queue mode fits records that represent independent work. Separate image conversions may finish in either order, while sequential state updates for the same entity can produce a different result when reversed.
| Decision point | Stream mode | Queue mode |
|---|---|---|
| Processing order within a partition | Guaranteed | Not guaranteed |
| Work distribution | Exclusive partition assignment | Records from a partition are shared |
| Suitable workloads | Order-dependent CDC and event sourcing | Independent transformations and background jobs |
An acquired record is protected from other consumers by its lock and acknowledged after successful processing. Lambda pollers renew locks while processing continues; records from failed invocations become eligible for redelivery. Expiring locks let another consumer take over when the original worker is lost.
A lock does not guarantee exactly-once business effects. Lambda ESMs use at-least-once delivery, so functions need to be idempotent. As a design example, consider a converted image being saved before an invocation fails: repeating that job should not corrupt the result.
Redelivery also involves both Lambda's MaximumRetryAttempts and Kafka's group.share.delivery.count.limit. The latter limits delivery attempts in the Kafka 4.2 broker configuration. For configurations that use a Kafka topic, SQS, or SNS as an on-failure destination, deliberately trigger failures and observe both redelivery and arrival at the destination.
Align the Queue mapping with Kafka requirements and starting positions
The feature applies to Self-managed Apache Kafka ESMs connecting to Kafka 4.2 or later with share groups enabled. This can include compatible third-party managed Kafka services as well as clusters you operate yourself. The Lambda Developer Guide, checked on November 3, 2026, excludes Amazon MSK.
The minimum supported version is separate from choosing an operational patch release. The Kafka upgrade guide records a fix for a share group deadlock in 4.2.1. Review fixes in the release line you intend to run instead of treating the 4.2 minimum as a complete version-selection policy.
The relevant configuration fragment for creating a Queue mapping is shown below. It is not a complete creation request: combine it with broker endpoints, topic, function, and the required networking and authentication settings.
{
  "SelfManagedKafkaEventSourceConfig": {
    "ConsumptionMode": "Queue"
  }
}
Omitting ConsumptionMode retains the default Stream behavior; existing mappings do not automatically become Queue mappings. Queue mode does not accept StartingPosition, StartingPositionTimestamp, or MaximumBatchingWindowInSeconds. Apply these Queue configuration constraints before reusing an existing configuration.
Pay particular attention to where consumption begins. In the Kafka 4.2 group configuration, share.auto.offset.reset, which initializes a new share group's starting position, defaults to latest. If a test needs to process an existing backlog, creating the mapping alone is not a reason to expect old records to be replayed. Plan the starting position together with the group's existing consumption state.
Pollers and broker limits become the next capacity boundaries
Removing the partition-count constraint does not make capacity unlimited. Queue mode on demand reaches its limit at either 5 MB/s or 50 concurrent invocations across the ESM, whichever comes first. Provisioned mode supports up to 5 MB/s and ten concurrent invocations per poller, with additional Event Poller Unit, or EPU, charges. The scaling-mode comparison distinguishes these aggregate and per-poller limits.
For a target of 300 concurrent invocations, the concurrency-only lower bound is 300 ÷ 10 = 30 pollers. This is a starting point for considering ingress bandwidth, execution time, and downstream capacity, rather than a measured performance guarantee.
Kafka 4.2 also sets group.share.max.size to 200 by default, with a configurable maximum of 1,000. Raising Lambda's MaximumPollers cannot bypass the broker's membership limit. Include the per-partition in-flight record limit, group.share.partition.max.record.locks, when planning capacity using the broker configuration reference.
The first adoption decision is whether each job can run independently. If it can, test reversed order and redelivery, then gradually increase poller and downstream capacity while measuring the backlog. Queue mode provides a way to tune processing capacity for independent Kafka jobs separately from the topic's partition layout.
Source
- Title: Introducing queue consumption mode for Apache Kafka in AWS Lambda
- URL: https://aws.amazon.com/blogs/compute/introducing-queue-consumption-mode-for-apache-kafka-in-aws-lambda/
Share
Related Articles
These articles share nearby categories or tags, so you can keep reading along the same thread.